

你有数千份文档,需要找到回答某个特定问题的那一份。那么该怎么找到它?
首先,用一种快速方法(比如关键词匹配)把数千个候选削减为一个合理的短列表。我们称之为快速检索(fast search)。
快速检索擅长做这件事,但它说不出短列表上哪个候选才是正确的。这正是重排序的用武之地:它把短列表上的每个候选直接与查询比对打分,把最好的排在最前面。
下面的两个步骤都在来自 CLERC 数据集的 3,565 个法院判决意见段落上运行:BM25 为 40 个查询中的每一个构建一个含 30 个候选的快速检索短列表,然后 TypeSafe 对每个短列表重排序。有了重排序,18% 的查询中正确段落排在第一位,而仅用快速检索时这一比例是 5%。
在这个过程中,你将学到:
- 快速检索做了什么,以及为什么它不等于全部答案
- 重排序是什么,以及它如何衔接在快速检索步骤之后
- TypeSafe 如何针对查询为一个候选打分,以及这能给结果带来多大提升
亲手试试
在 TypeSafe Playground 中打开一个查询、候选和重排序问题
怎样在数千份文档中找到那一份?
你有一堆文档,还有一个查询,即一段描述你要找什么的文本。这堆文档中的某处,正是回答它的那一份文档。
把每份文档逐一与查询比对是可行的,代价是每份文档一次比对:数百万份文档意味着每个查询要数百万次比对。你可以用两步法提升性能:
- 用一种快到能跑遍整个文档堆的方法,把文档堆削减为一个可能候选的短列表。
- 再对这个短列表应用一个更精确的步骤,找出确切正确的答案。

本实战指南在一个法院判决意见数据集上测试这套设置,见下文在真实示例上重排序一节。
什么是快速检索?
快速检索是任何能把查询与大型语料库中的每份文档比对、并快速返回一个有序短列表的方法。常见方法包括关键词检索(例如 BM25),以及按语义比较段落的稠密嵌入(dense embedding)。系统常常将两种方法结合使用。
这里的第一步只用 BM25,别无其他。BM25 按共享词汇为段落排序。保持这一步简单,是为了把注意力留给重排序——那才是本实战指南的重点。选择哪种快速检索方法只是支线问题:重排序看到的永远只是进入短列表的段落。
什么是重排序?
重排序拿过快速检索已经产出的短列表,把它排成更好的顺序。它不是把查询与整个语料库一次性比对,而是把查询与短列表上的每个候选逐个比对,并按该分数对短列表排序。
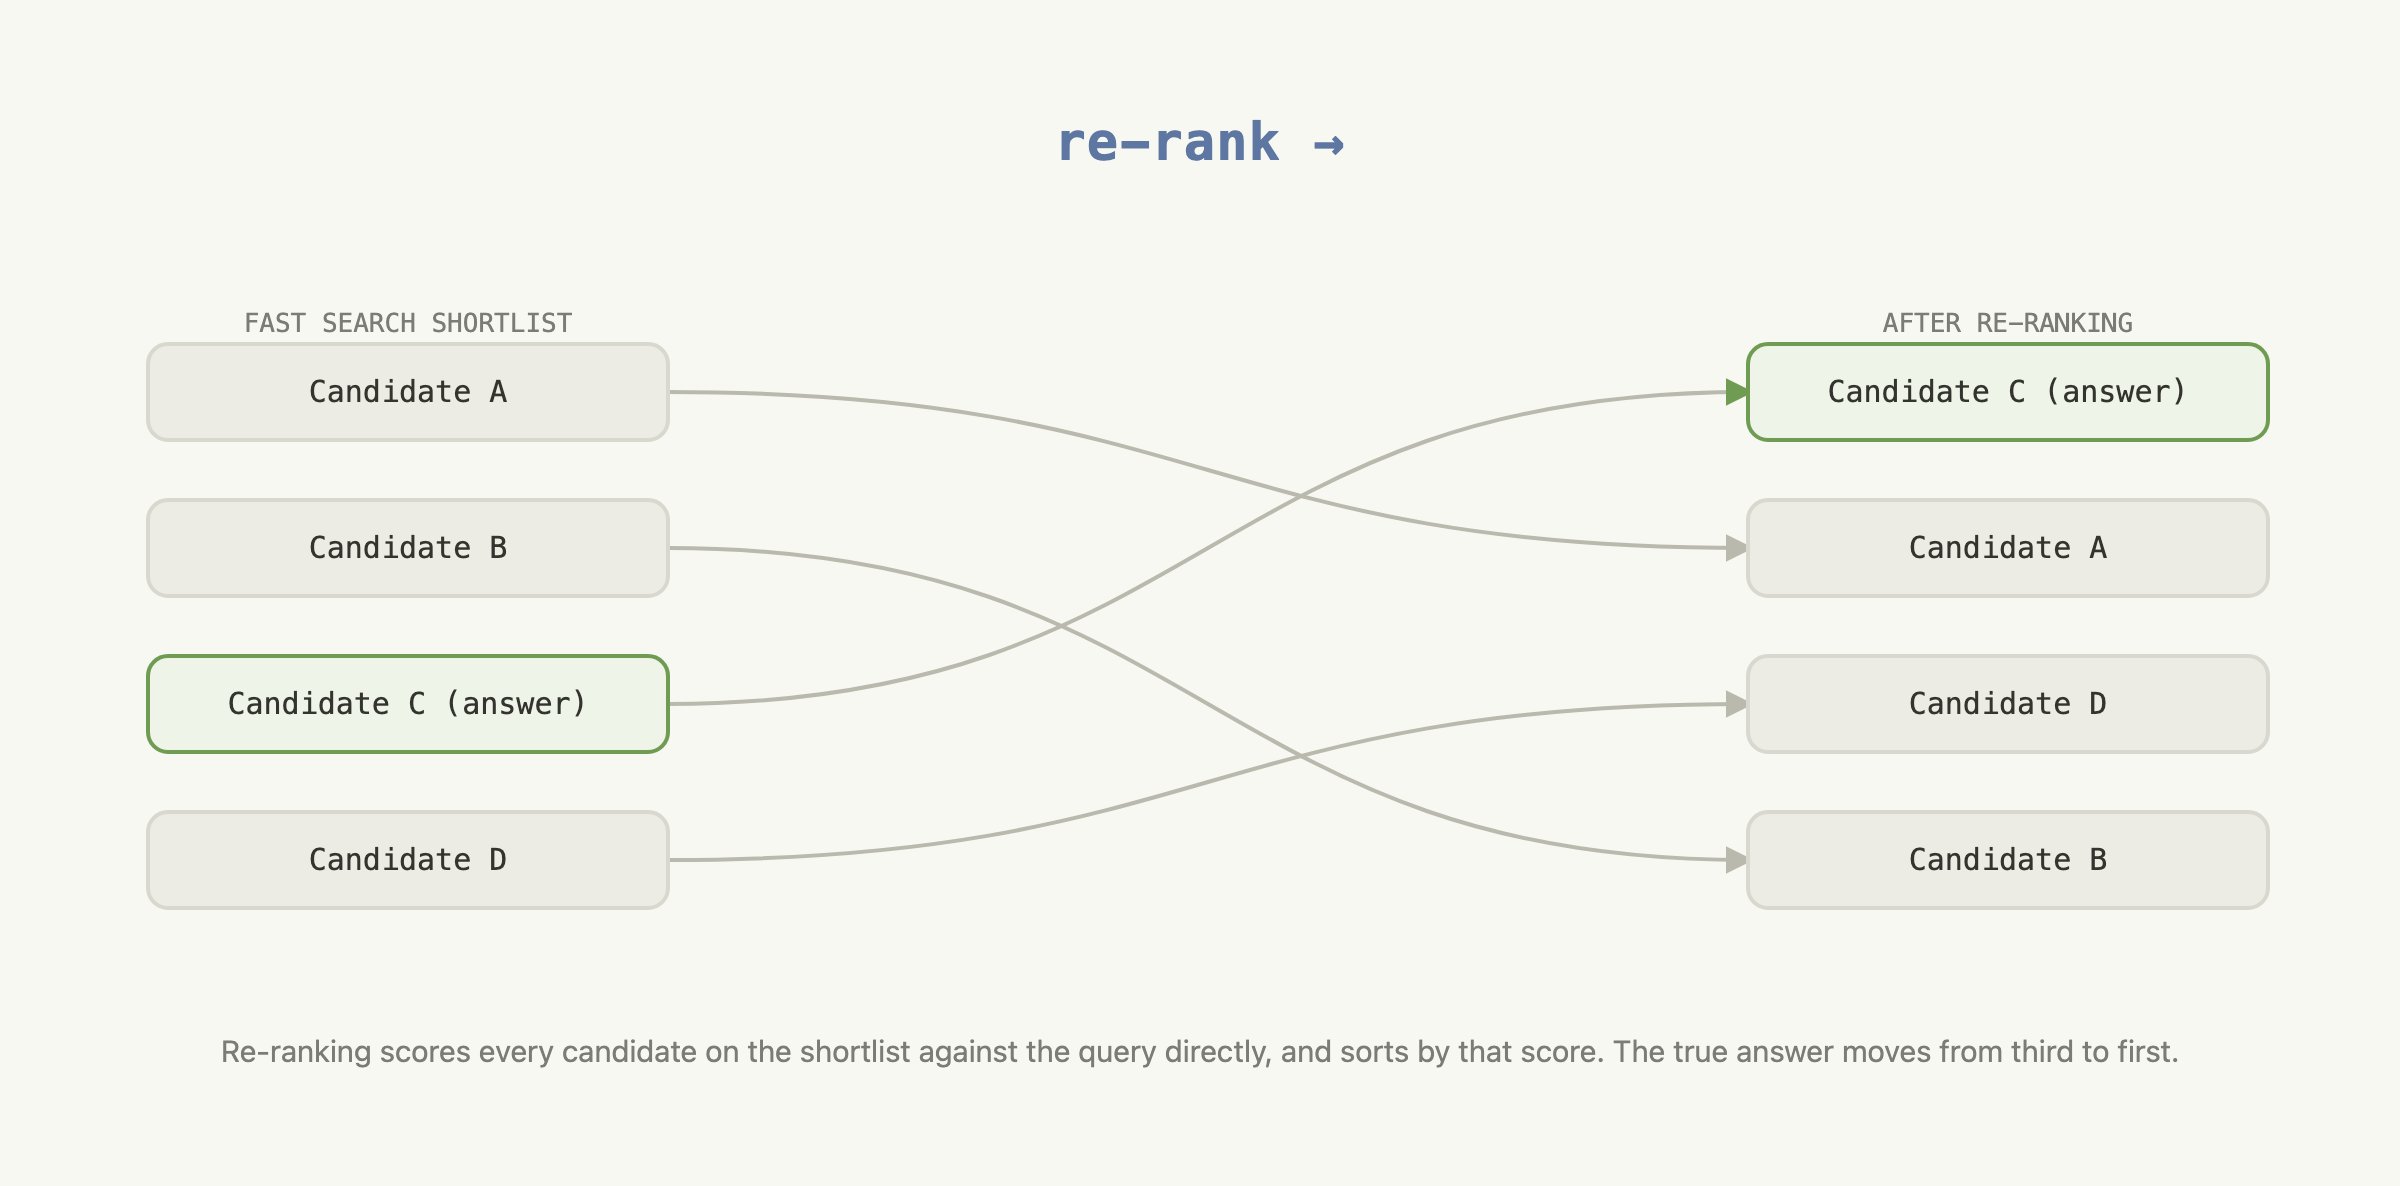
分数可以来自语言模型。把查询和一个候选一起交给它,询问该候选对查询的回答程度。这样,即使最佳匹配的措辞与查询不同,重排序也能在短列表上把它找出来。
用 TypeSafe 做重排序
重排序器需要为每个“查询-候选”对提供一个可比较的分数。通用语言模型可以产生这些分数,也可以直接对整个短列表排序。但是,要做独立的逐对打分,你需要定义一套评分量表,并提示模型对每个候选应用同一标准。即便如此,重复调用仍可能对同一对给出不同的分数,而通用文本生成为这个只需要一个数字的任务平添时间和成本。
TypeSafe 返回什么
有了 TypeSafe,打分请求可以仍然是一个是/否问题:
Could this candidate passage be from the cited precedent?
单纯的“是”或“否”不足以给 30 个候选排序。Noul 则返回一个 0 到 1 之间的数字,称为 noul。这个 noul 是 TypeSafe 对“答案为是”的可能性的估计。
问题的标准定义了什么算真、什么算假。TypeSafe 把它们应用到每个“查询-候选”对上,并直接返回 noul。这个 noul 就是应用排序所依据的分数。既不需要为通用模型发明评分量表,TypeSafe 本身也是为更快、更便宜、更一致地完成这种重复打分而构建的。
用简化的伪代码表示,一次 TypeSafe 打分调用如下所示:
question = Noul(
    instructions="Is this candidate the cited case?",
    criteria=NoulCriteria(
        true="The candidate states the specific rule the query cites.",
        false="The candidate is only on a similar topic.",
    ),
)
response = client.system_one(state={...}, questions={"is_cited_source": question})
response.answers["is_cited_source"].noul  # -> 0.87
TypeSafe 依据该问题把查询和一个候选放在一起读取,并返回一个 noul。
你可以据此对短列表重排序:对短列表上的每个候选运行同一个问题,然后按每次调用返回的 noul 对短列表排序,最高者在前。
nouls = {candidate: ask_typesafe(query, candidate) for candidate in shortlist}
reranked = sorted(shortlist, key=lambda c: nouls[c], reverse=True)  # highest noul first
下图展示了“每个候选一次请求”如何产生用于重新排序短列表的分数。
一个重排序示例
接下来,快速检索与重排序在 CLERC(一个法律检索数据集)上运行。本示例使用 3,565 个法院判决意见段落和 40 个查询。
准备工作
第一步安装本演练依赖的软件包。
bm25s和datasets构建快速检索短列表。typesafe-sdk和cooksafe负责重排序和 API 缓存。matplotlib绘制结果图表。
pip install bm25s datasets matplotlib "typesafe-sdk>=0.5.7" cooksafe --extra-index-url https://pypi.typesafe.ai/
下一块代码设置 TypeSafe 客户端,以及演练其余部分会用到的常量,比如调用哪个 TypeSafe 模型、快速检索交给重排序器的短列表有多大。调用 TypeSafe 需要一个 TYPESAFE_API_KEY。
import hashlib
import json
import os
import random
from concurrent.futures import ThreadPoolExecutor
from pathlib import Path

import msgspec
from cooksafe import JsonCache
from IPython.display import display
from typesafe_sdk import Noul, NoulCriteria, TypeSafeClient

TYPESAFE_MODEL = "jev-1.12"
PRICE = (
    0.042,
    0.00,
)  # $ per 1M tokens (input, output); TypeSafe jev-1.12 as of 2026-08
N_ROWS = 170  # CLERC rows pooled into the shared corpus
N_QUERIES = 40  # rows we evaluate
TOP_K = 30  # candidates the shortlist hands to the re-ranker, per query

client = TypeSafeClient(
    api_key=os.environ.get(
        "TYPESAFE_API_KEY", "cache-only"
    ),  # keyless kernels replay the cache
    base_url=os.environ.get("TYPESAFE_ENDPOINT"),
    timeout=120.0,
)
json_cache = JsonCache(Path("json_cache.json"))
用快速检索为段落排序
这里使用的数据集是一个美国法院判决意见语料库,由 170 行汇集而成。每一行的构成如下:
- 查询(Query):一段移除了某条引文的判决意见摘录。
- 标准答案(Gold):被移除的引文所指向的段落,即该查询唯一正确的答案。
- 候选(Candidates):语料库中的其余所有段落,每一个都是查询可能被错误匹配到的对象。
170 行中有 40 行被选出作为查询进行评估,其余 130 行只会作为候选出现。
下一个单元格使用上文描述的技术构建短列表:
- 加载语料库。
- 用 BM25 按每个查询为语料库排序。
这里还没有 TypeSafe,这只是快速检索步骤。
CLERC_FILE = (
    "https://huggingface.co/datasets/jhu-clsp/CLERC/resolve/main/"
    "teva_train_dir/train_data.jsonl.gz"
)


def cid(text: str) -> str:
    """Corpus id: a content hash, so passages shared across queries dedupe."""
    return hashlib.sha1(text.encode("utf-8")).hexdigest()[:16]


@json_cache
def build_slice(n_rows: int, n_queries: int, seed: int) -> dict:
    """Stream CLERC rows, pool ``n_rows`` of them into a corpus, pick ``n_queries`` to evaluate."""
    from datasets import load_dataset  # heavy import, keep local

    stream = load_dataset("json", data_files=CLERC_FILE, streaming=True, split="train")
    rows = []
    for row in stream:
        if (
            row.get("positive_passages")
            and len(row.get("negative_passages") or []) == 20
        ):
            rows.append(row)
        if len(rows) >= 1000:
            break

    rng = random.Random(seed)
    picked = rng.sample(rows, n_rows)
    corpus, pool = {}, []
    for row in picked:
        gold = row["positive_passages"][0]["text"]
        corpus[cid(gold)] = gold
        for neg in row["negative_passages"]:
            corpus[cid(neg["text"])] = neg["text"]
        pool.append(
            {"qid": str(row["query_id"]), "query": row["query"], "gold": cid(gold)}
        )
    # hold out the first 20 pooled rows; evaluate on the rest
    queries = rng.sample(pool[20:], n_queries)
    # sort the corpus by id so every run — live or cache replay — iterates it identically
    return {"queries": queries, "corpus": dict(sorted(corpus.items()))}


def bm25_rankings(corpus: dict[str, str], queries: dict[str, str], k: int = 100):
    """Rank every passage in the corpus by word overlap with each query."""
    import bm25s

    cids = list(corpus)
    retriever = bm25s.BM25()
    retriever.index(bm25s.tokenize([corpus[c] for c in cids], stopwords="en"))
    qids = list(queries)
    idxs, _ = retriever.retrieve(
        bm25s.tokenize([queries[q] for q in qids], stopwords="en"), k=min(k, len(cids))
    )
    return {q: [cids[i] for i in idxs[row]] for row, q in enumerate(qids)}


def gold_rank(ranked: list[str], gold: str) -> int | None:
    """1-based rank of the gold id, or None if it isn't in the list."""
    return ranked.index(gold) + 1 if gold in ranked else None


SURFACE, INK, INK2, MUTED = "#f8f8f2", "#34342f", "#34342f", "#7c7c77"
GRID, AXIS, BLUE, GREEN = "#d8d8cf", "#d8d8cf", "#5d76a2", "#6f9b52"


def bar_chart(labels: list[str], shares: list[float], title: str) -> None:
    """A small single-series bar chart of shares (0-1, shown as percentages)."""
    import matplotlib.pyplot as plt

    fig, ax = plt.subplots(figsize=(5, 3.2), facecolor=SURFACE)
    ax.set_facecolor(SURFACE)
    for side in ("top", "right"):
        ax.spines[side].set_visible(False)
    for side in ("left", "bottom"):
        ax.spines[side].set_color(AXIS)
    ax.tick_params(colors=MUTED, labelcolor=INK2, labelsize=9)
    ax.set_axisbelow(True)
    ax.grid(axis="y", color=GRID, linewidth=0.8)

    bars = ax.bar(labels, shares, width=0.55, color=[BLUE, GREEN][: len(labels)])
    ax.bar_label(
        bars,
        labels=[f"{s * 100:.0f}%" for s in shares],
        padding=4,
        color=INK,
        fontsize=11,
    )
    ax.set_ylim(0, 1.1)
    ax.set_yticks([0, 0.25, 0.5, 0.75, 1.0])
    ax.set_yticklabels(["0%", "25%", "50%", "75%", "100%"])
    ax.set_ylabel(f"share of {len(queries)} queries", color=INK2, fontsize=9)
    ax.set_title(title, loc="left", color=INK, fontsize=11)
    plt.tight_layout()
    display(fig)
    plt.close(fig)


ds = build_slice(N_ROWS, N_QUERIES, seed=0)
corpus: dict[str, str] = ds["corpus"]
queries = {q["qid"]: q["query"] for q in ds["queries"]}
golds = {q["qid"]: q["gold"] for q in ds["queries"]}

candidates = {q: ranked[:TOP_K] for q, ranked in bm25_rankings(corpus, queries).items()}

in_top_k = sum(golds[q] in candidates[q] for q in queries)
at_rank_1 = sum(candidates[q][0] == golds[q] for q in queries)

bar_chart(
    [f"In top {TOP_K}", "At rank 1"],
    [in_top_k / len(queries), at_rank_1 / len(queries)],
    f"Where the correct passage lands, {len(queries)} queries against {len(corpus):,} candidates",
)
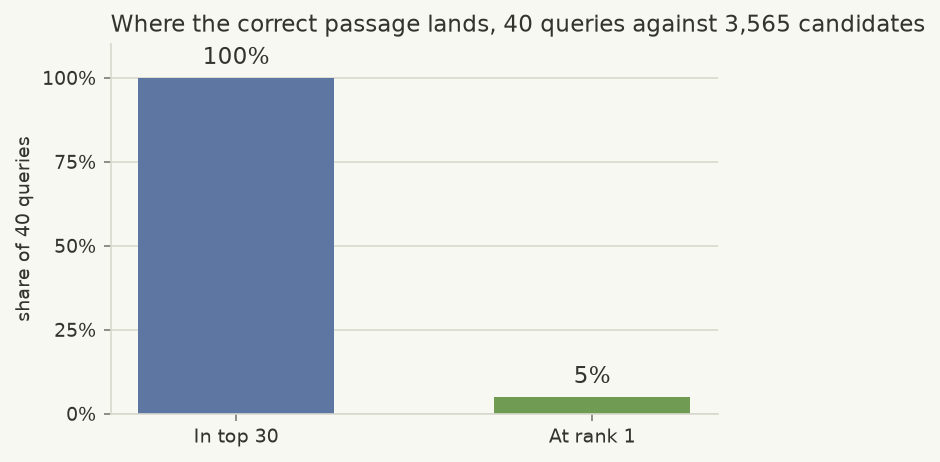
快速检索不太可能把正确段落排在第一
图表显示了在 3,565 个候选中,快速检索把正确段落放在了什么位置。
快速检索可靠地把语料库缩小到包含正确答案的短列表:40 个查询的短列表全部包含正确答案。但那个段落很少是短列表上排名第一的,只有 5% 的时间。
下方的重排序只对短列表上已有的前 30 个候选重新排序,它无法添加快速检索没有选中的段落。在这里,所有 40 个查询的短列表都包含正确段落,因此重排序可以专注于把每个正确段落放到更好的位置。
用 TypeSafe 对它重排序
重排序把短列表上的每个候选与其查询比对打分,然后按该分数排序。TypeSafe 对每一对提出的问题是:该候选是否可能是查询中被移除的引文所指向的段落。
下一个单元格做以下事情:
- 定义该问题。
- 对每个短列表上的每个候选各提问一次——40 个查询乘以 30 个候选,共 1,200 次调用——并发执行而非逐个执行。
- 按 TypeSafe 返回的分数对每个短列表排序,得到重排序结果。
is_cited_source = Noul(
    instructions=(
        "The query excerpt comes from a US federal court opinion and was written "
        "immediately around a citation to a precedent; the citation itself has been "
        "removed. Could the candidate passage be from that cited precedent — does it "
        "establish the specific legal proposition the query excerpt invokes at its "
        "citation point?"
    ),
    criteria=NoulCriteria(
        true=(
            "The candidate passage states or establishes the specific rule, standard, "
            "holding, or fact pattern that the query excerpt attributes to its removed "
            "citation."
        ),
        false=(
            "The candidate passage is merely on a similar topic or doctrine; it does not "
            "supply the specific proposition the query excerpt relies on."
        ),
    ),
)


@json_cache
def score_candidate(model: str, query: str, candidate: str, question_json: str) -> dict:
    """One TypeSafe call about one (query, candidate) pair: a noul, plus token usage."""
    # the SDK takes a question as its JSON dict, so the cached string decodes straight in
    question = json.loads(question_json)
    response = client.system_one(
        state={"query_excerpt": query, "candidate_passage": candidate},
        questions={"is_cited_source": question},
        model=model,
    )
    return {
        "noul": response.answers["is_cited_source"].noul,
        "input_tokens": response.usage.input_tokens or 0,
        "output_tokens": response.usage.output_tokens or 0,
    }


# Each of the 40 queries has 30 candidates, so re-ranking every shortlist means 1,200 independent
# calls — cheap enough to fire all at once with a thread pool instead of one after another.
pair_list = [(q, c) for q in queries for c in candidates[q]]
question_json = msgspec.json.encode(is_cited_source).decode()
with ThreadPoolExecutor(max_workers=12) as pool:
    results = pool.map(
        lambda p: score_candidate(
            TYPESAFE_MODEL, queries[p[0]], corpus[p[1]], question_json
        ),
        pair_list,
    )
pair_scores = {q: {} for q in queries}
for (q, c), result in zip(pair_list, results):
    pair_scores[q][c] = result

reranked = {
    q: sorted(candidates[q], key=lambda c: -pair_scores[q][c]["noul"]) for q in queries
}


def chart_before_after(
    runs: dict[str, dict[str, list[str]]], thresholds: list[int]
) -> None:
    """Grouped bar chart: how often the correct passage lands in the top N, for each run."""
    import numpy as np
    import matplotlib.pyplot as plt

    labels = list(runs)
    colors = [BLUE, GREEN]

    def share_in_top(rankings, k):
        return sum(
            gold_rank(rankings[q], golds[q]) in range(1, k + 1) for q in queries
        ) / len(queries)

    fig, ax = plt.subplots(figsize=(6.5, 3.6), facecolor=SURFACE)
    ax.set_facecolor(SURFACE)
    for side in ("top", "right"):
        ax.spines[side].set_visible(False)
    for side in ("left", "bottom"):
        ax.spines[side].set_color(AXIS)
    ax.tick_params(colors=MUTED, labelcolor=INK2, labelsize=9)
    ax.set_axisbelow(True)
    ax.grid(axis="y", color=GRID, linewidth=0.8)

    x = np.arange(len(thresholds))
    width = 0.35
    for i, (label, rankings) in enumerate(runs.items()):
        shares = [share_in_top(rankings, k) for k in thresholds]
        offset = (i - (len(labels) - 1) / 2) * width
        bars = ax.bar(x + offset, shares, width * 0.92, color=colors[i], label=label)
        ax.bar_label(
            bars,
            labels=[f"{s * 100:.0f}%" for s in shares],
            padding=3,
            color=INK2,
            fontsize=8.5,
        )

    ax.set_xticks(x, [f"top {k}" for k in thresholds])
    ax.set_ylim(0, 1)
    ax.set_yticks([0, 0.25, 0.5, 0.75, 1.0])
    ax.set_yticklabels(["0%", "25%", "50%", "75%", "100%"])
    ax.set_ylabel(f"share of {len(queries)} queries", color=INK2, fontsize=9)
    ax.set_title(
        "How often the correct passage lands near the top",
        loc="left",
        color=INK,
        fontsize=11,
    )
    ax.legend(frameon=False, labelcolor=INK2, fontsize=9, loc="upper left")
    plt.tight_layout()
    display(fig)
    plt.close(fig)


chart_before_after(
    {"Fast search": candidates, "+ TypeSafe re-rank": reranked}, [1, 5, 10]
)

calls = [pair_scores[q][c] for q in queries for c in pair_scores[q]]
input_tokens = sum(call["input_tokens"] for call in calls)
output_tokens = sum(call["output_tokens"] for call in calls)
cost = input_tokens / 1_000_000 * PRICE[0] + output_tokens / 1_000_000 * PRICE[1]
print(
    f"{len(calls)} TypeSafe calls used {input_tokens:,} input and "
    f"{output_tokens:,} output tokens, costing ${cost:.4f}."
)
1200 TypeSafe calls used 1,536,002 input and 25,200 output tokens, costing $0.0645.
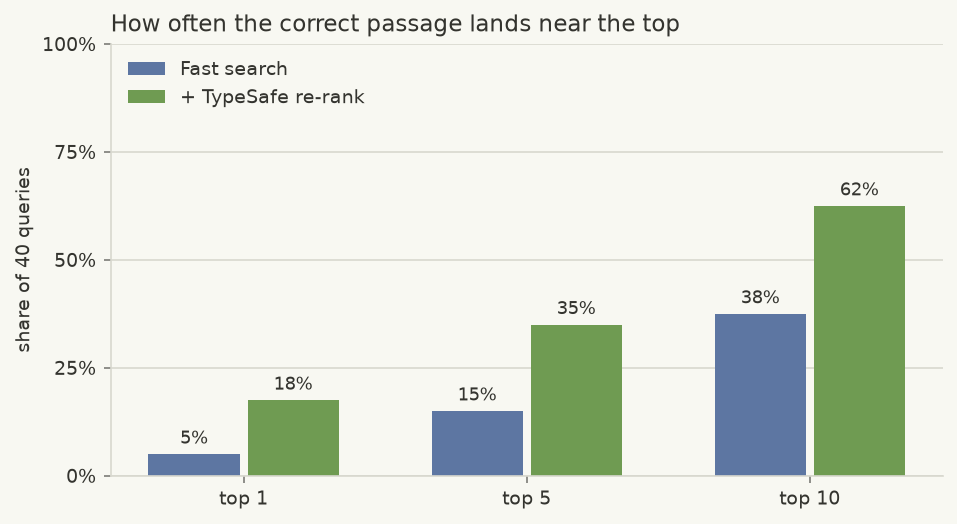
重排序把正确答案推向顶部
图表在三个阈值上比较快速检索与“快速检索 + 重排序”。在每一个阈值上,重排序都把正确段落推向更靠近顶部的位置:
- Top 1 — 5% → 18%
- Top 5 — 15% → 35%
- Top 10 — 38% → 62%
报告的 token 数量和成本覆盖了对 40 个短列表进行重排序所用的全部 1,200 次 TypeSafe 调用。
每个 CLERC 行包含一个正确段落和 20 个负例段落。本演练把来自 170 行的段落汇集到一个共享语料库。对 40 个评估查询中的每一个,BM25 都从完整语料库中选出 30 个候选,而不只是该行自带的 20 个负例。随后 TypeSafe 把查询与每个选中的候选对照读取,并对这 30 个段落重排序。
为清晰起见,本演练对每一对只问一个问题。真实的应用会在一次调用中对同一对提出多个问题,做法参见并行问题实战指南和投机性扇出模式。
接下来
同样的构建块也出现在 TypeSafe 文档的其他地方: